MorphMind | AgentLab
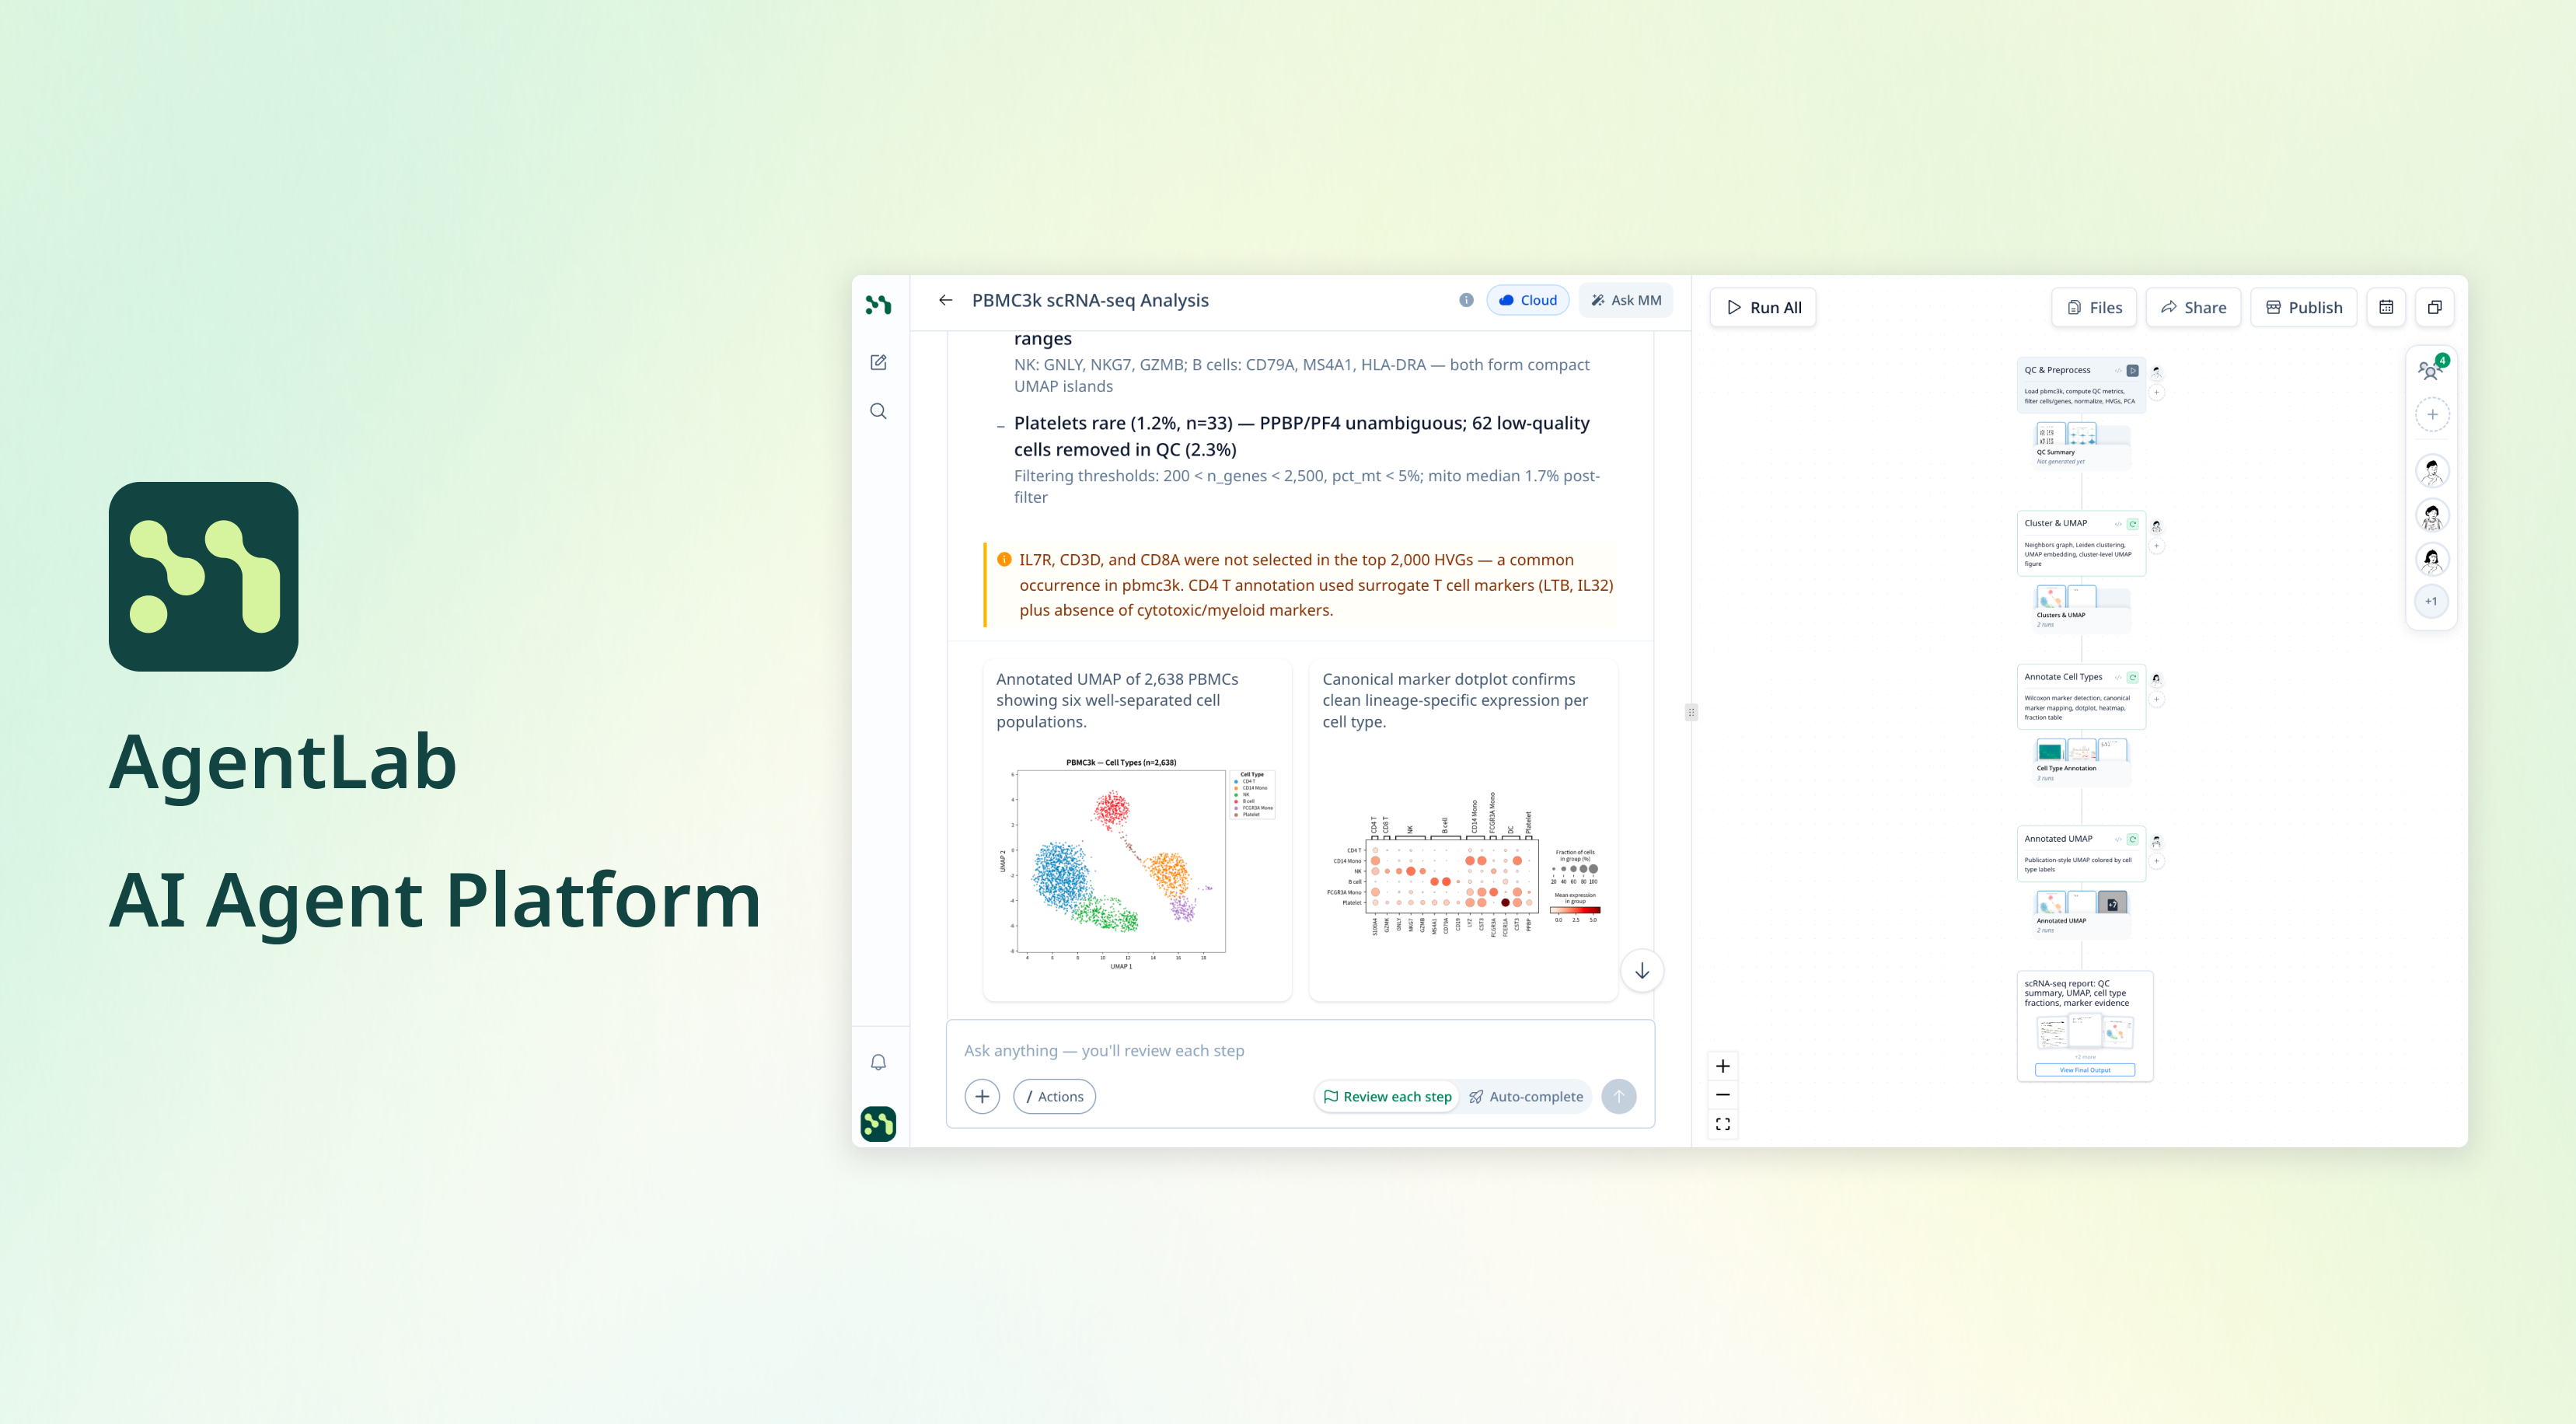
Project overview:
AgentLab is an AI agent platform that helps users create, control, deploy, and manage trustworthy autonomous agents to automate repeatable workflows by turning complex tasks into reusable agents that deliver desired outputs.
Designing the first-agent experience that made an AI platform launch-ready
Founding product designer on AgentLab, a VC-backed agentic AI platform for researchers and professionals doing complex knowledge work. We went from engineering demo to public launch in 6 months, including one roadmap call where we traded a headline feature for user activation, and one benchmark I had to rebuild after it told me the wrong thing.
My Role:
Founding Product Designer
Owned end-to-end UX direction across:
- Research & product strategy
- Agent creation flow & Plan Mode
- Chat, execution & specialist UX
- Define Success criteria & testing
My Design Impact:
First AI agent creation experience improved:
58.8% → 92.9% of users created an agent without help
38.2% → 89.3% received useful output they would use
Team:
Sole designer (+2 interns), 1 AI researcher, 2 engineers, CEO
Timeline:
0→1 · Sep 2025 – March 2026
6 months to launch
–The Setup-
The technology worked. The product didn’t.
AgentLab turns repeatable knowledge work (research, data analysis, reporting) into reusable AI agents. The engine already ran impressive multi-step workflows, but first-time users couldn’t reliably create an agent that produced what they wanted. My job was to define what a successful first agent looks like, measure it, and redesign creation around it.
The engineering demo I inherited
-Our Users-
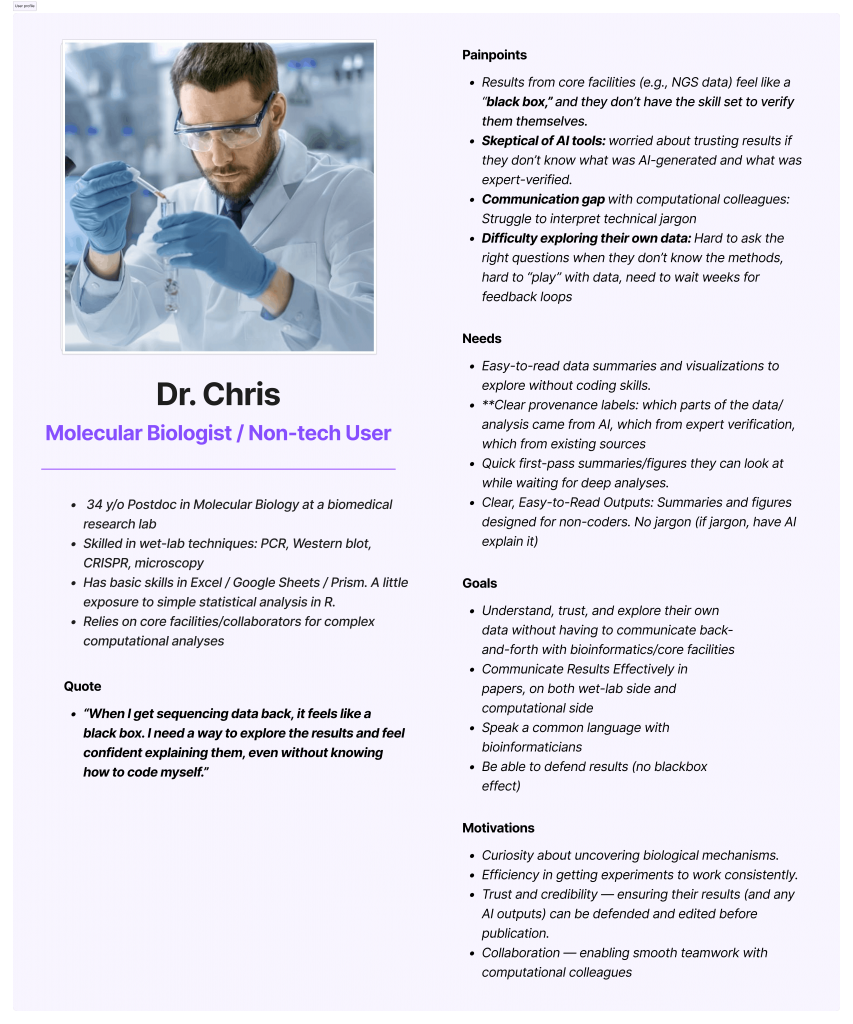
Two user types, one trust problem
8 interviews with researchers at MIT and Harvard labs surfaced two very different groups, and one shared blocker.
Non-technical researchers
Wet-lab researchers who understood the scientific question but relied on technical collaborators to analyze and interpret their data.
Technical researchers
Computational biology postdocs who could build analysis workflows, but needed reliable ways to save, rerun, and share them.
Core challenge: visibility into the analysis
- Results often felt like a black box they could not verify.
- They could not easily understand the methods or explore follow-up questions.
- Working with core facilities and bioinformatics teams created long feedback loops.
Core challenge: reliability & reproducibility
- Workflows were often tied to specific machines, environments, or clusters.
- Raw data came in inconsistent formats and often lacked metadata.
- Repeating the same analysis required rebuilding or manually maintaining the pipeline.
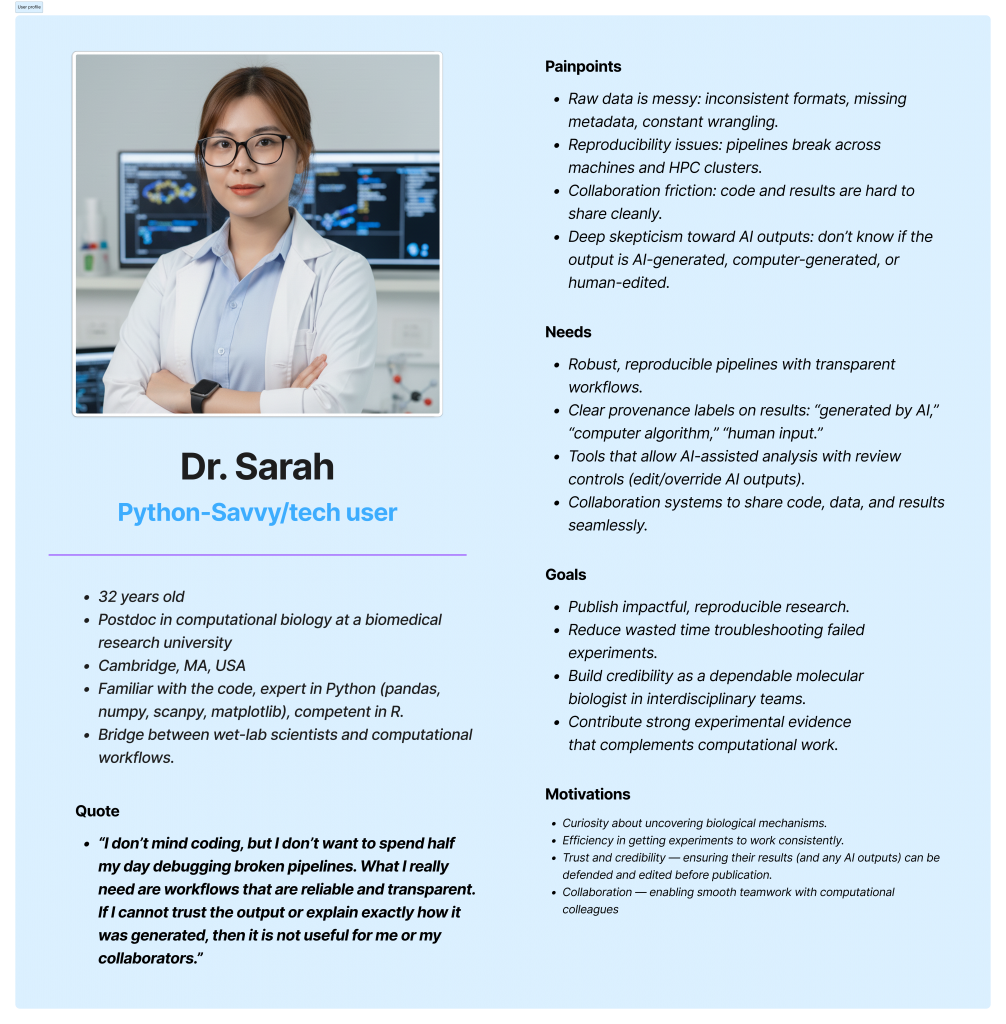
And the shared blocker: Both groups distrusted AI outputs when they could not see how the analysis was performed or where the results came from.
That’s the trust problem the product had to solve
Clarity
Non-technical researchers needed workflows explained in plain language, while technical researchers needed a way to review how the AI ran the analysis.
Transparency
Both groups needed to see how the agent interpreted the task, which methods it used, and where each output came from.
Reproducibility
Researchers needed to save and reuse the same workflow so they could repeat the analysis consistently across datasets, experiments, and collaborators.
– Design Challenge –
Turn an engineering-driven AI workflow into an experience researchers could understand, evaluate, trust, and reuse
– Early UI explorations for redesigning the platform –
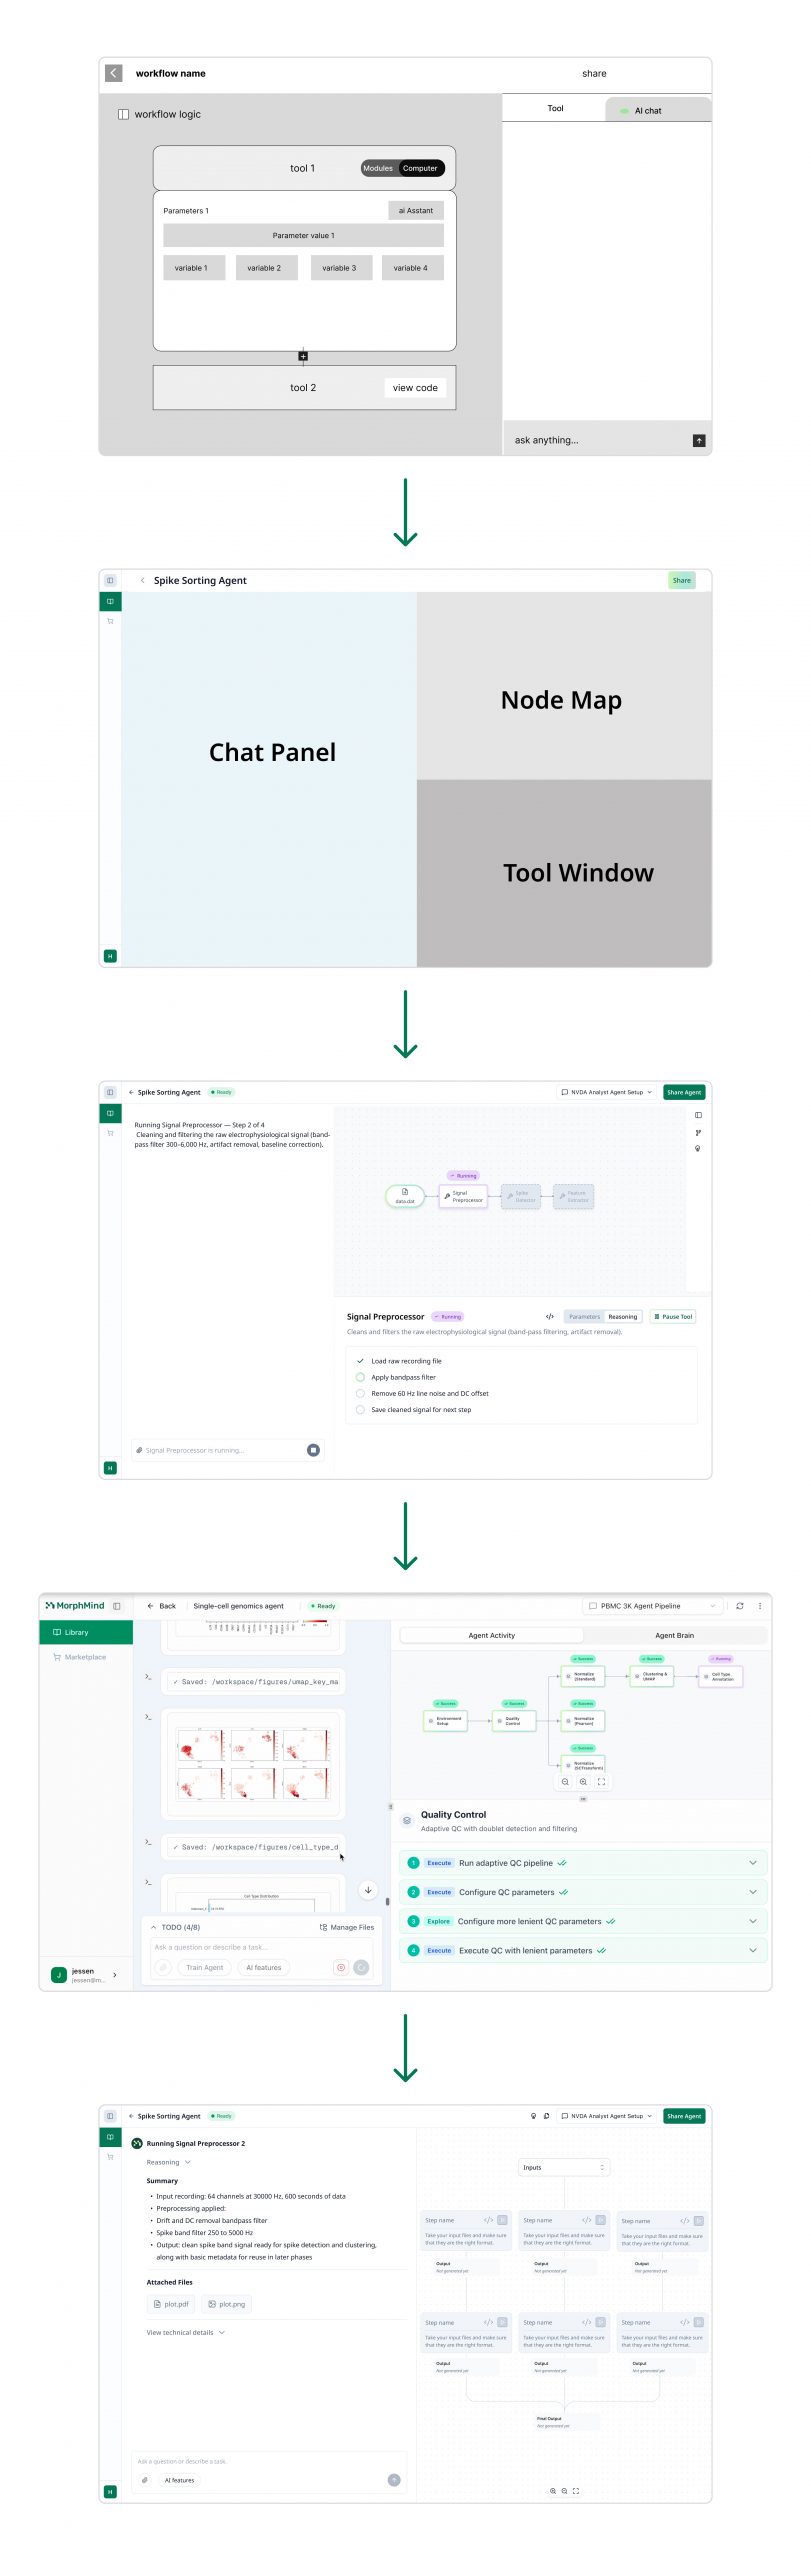
– Early product demo — midway through the early iterations –
– The Insight –
Users didn’t need better outputs.
They needed help defining the task
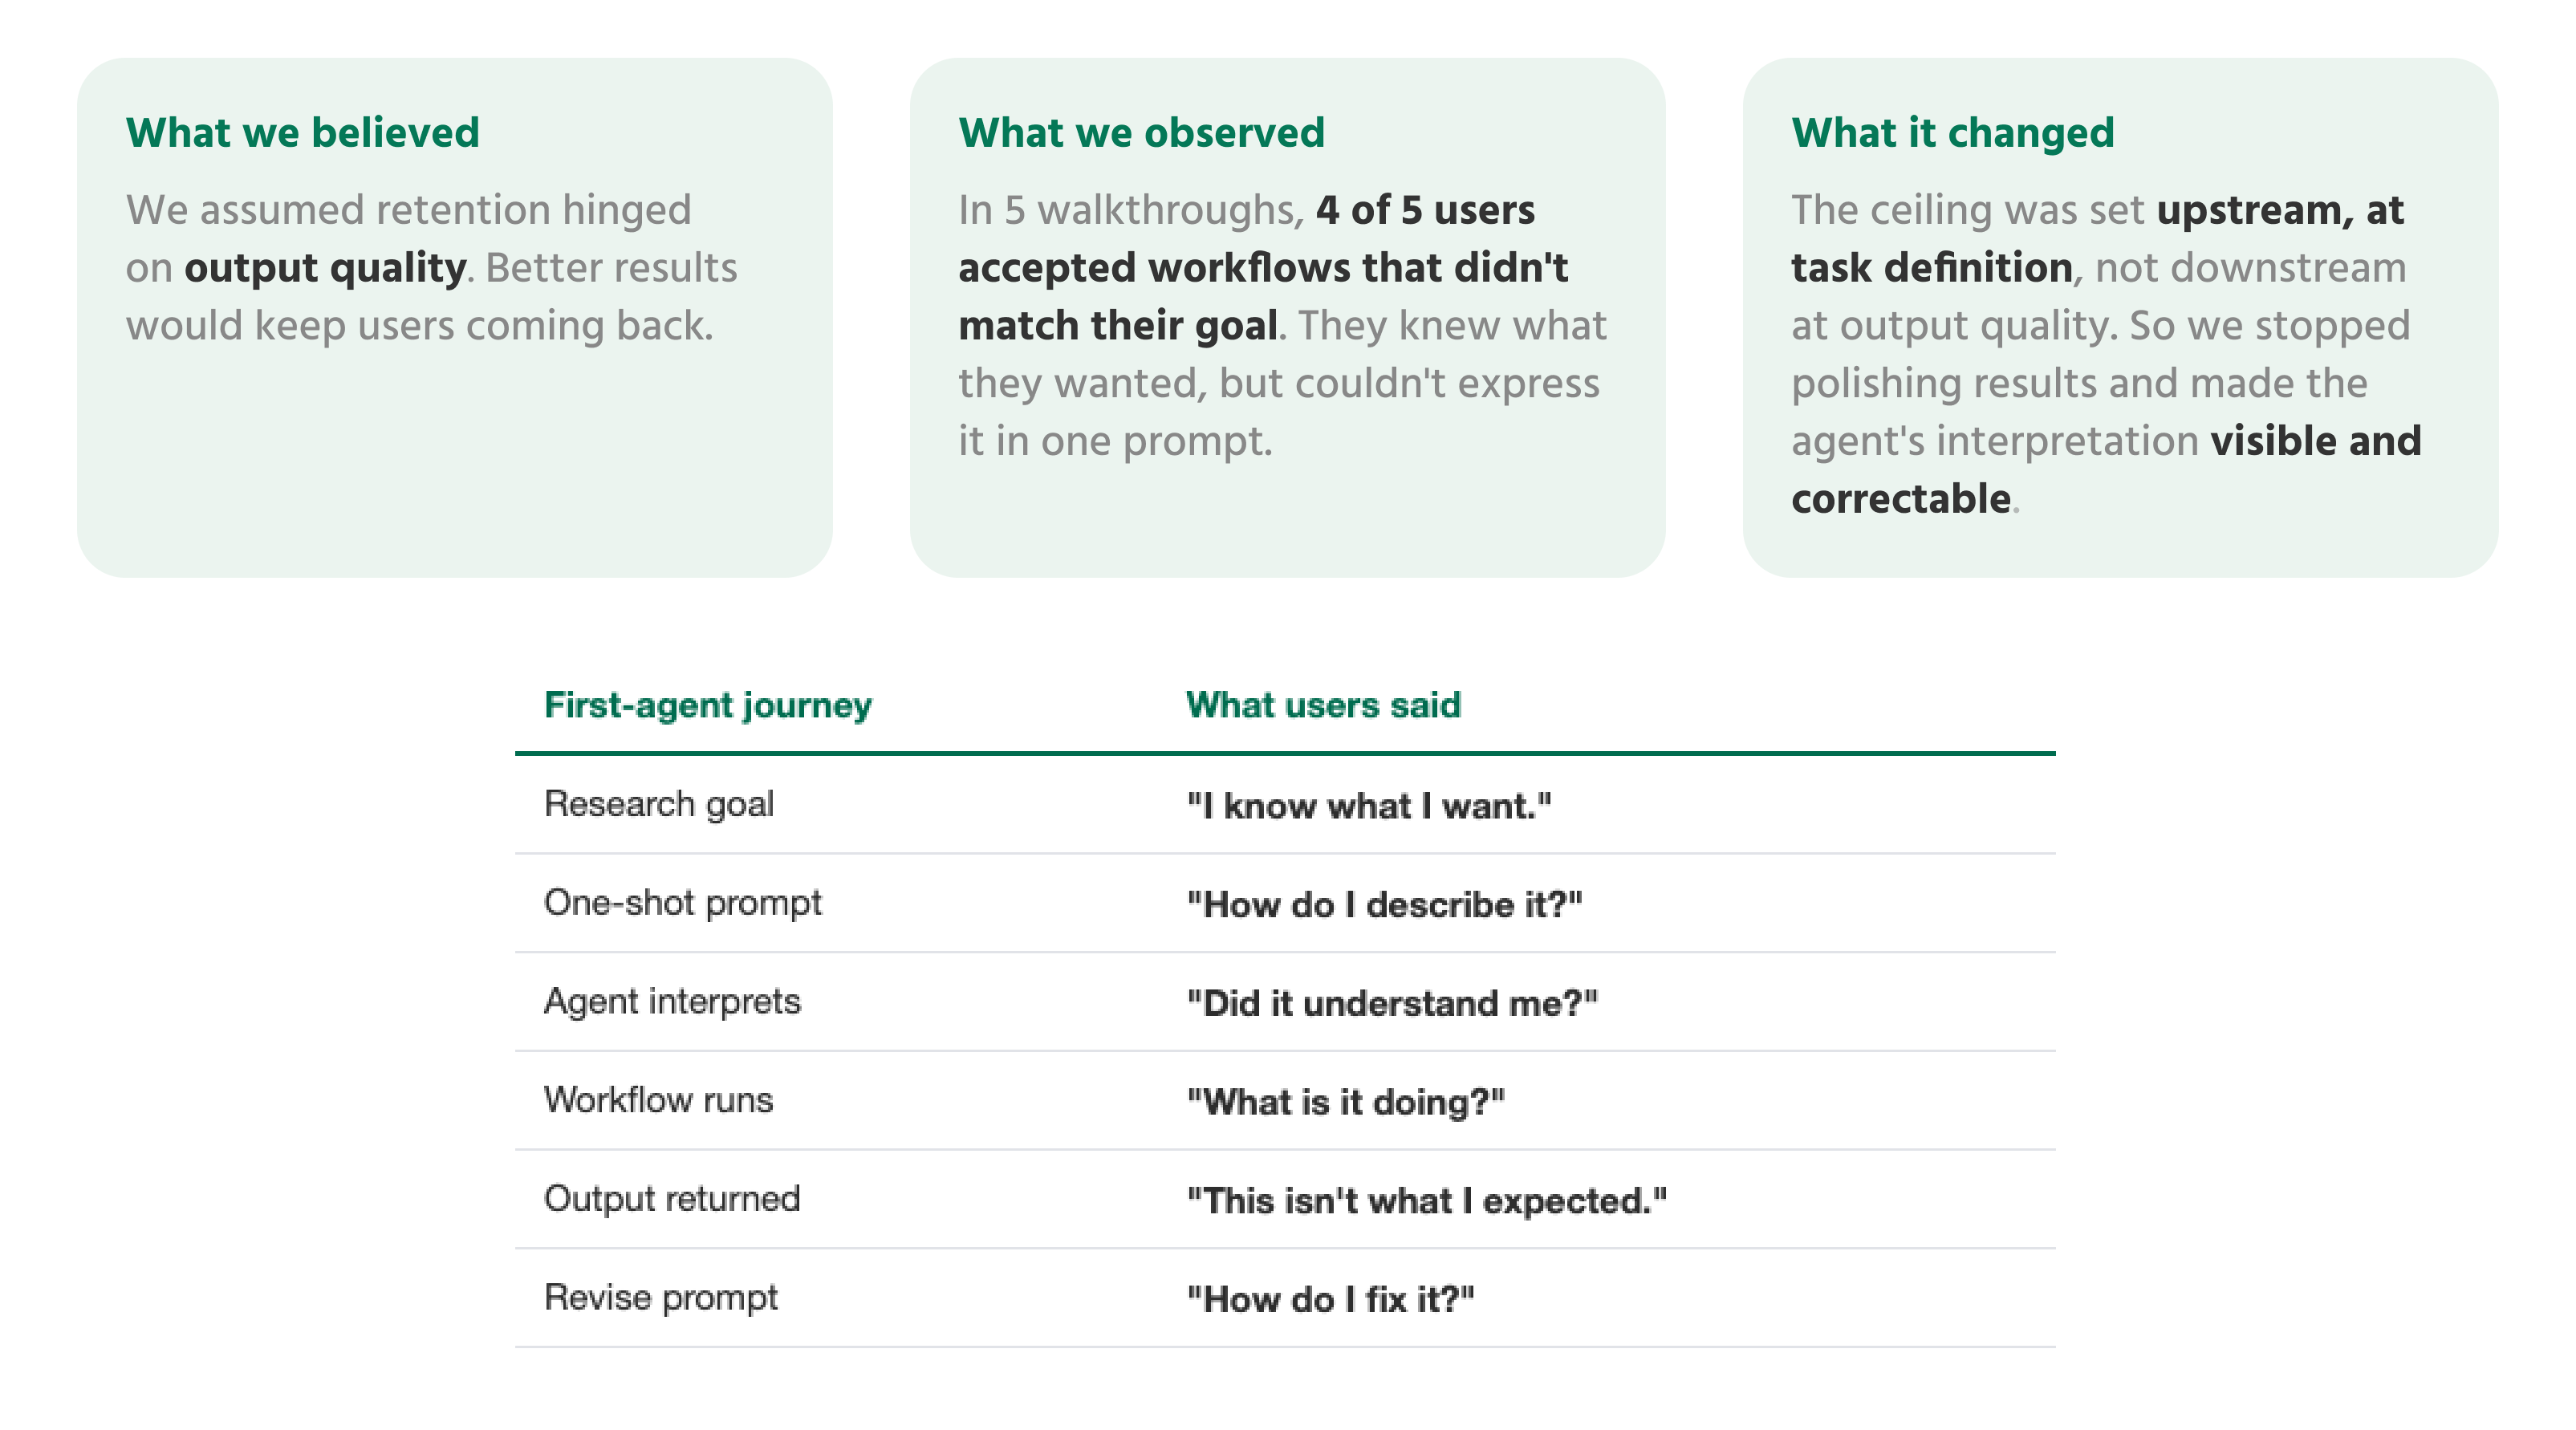
Several iterations turned the demo into a functioning product: better layout, clearer nodes, example prompts. Users could run the workflow. But the agent kept misunderstanding the goal, because it started before the user and the system had agreed on what the work actually was.
The failure was upstream of the output. So the redesign had to move upstream too: help users define the work before judging the result.
– The Turn –
Roadmap tension: collaboration before activation
Midway through the project, the CEO shifted the roadmap toward Teamspace. Two days into designing it, I stopped. Sharing only makes sense if people have agents worth sharing.
“If users cannot create and trust one useful agent, what are they collaborating around?”
And the quieter question behind it: “Am I helping us ship more features, or helping users succeed?”
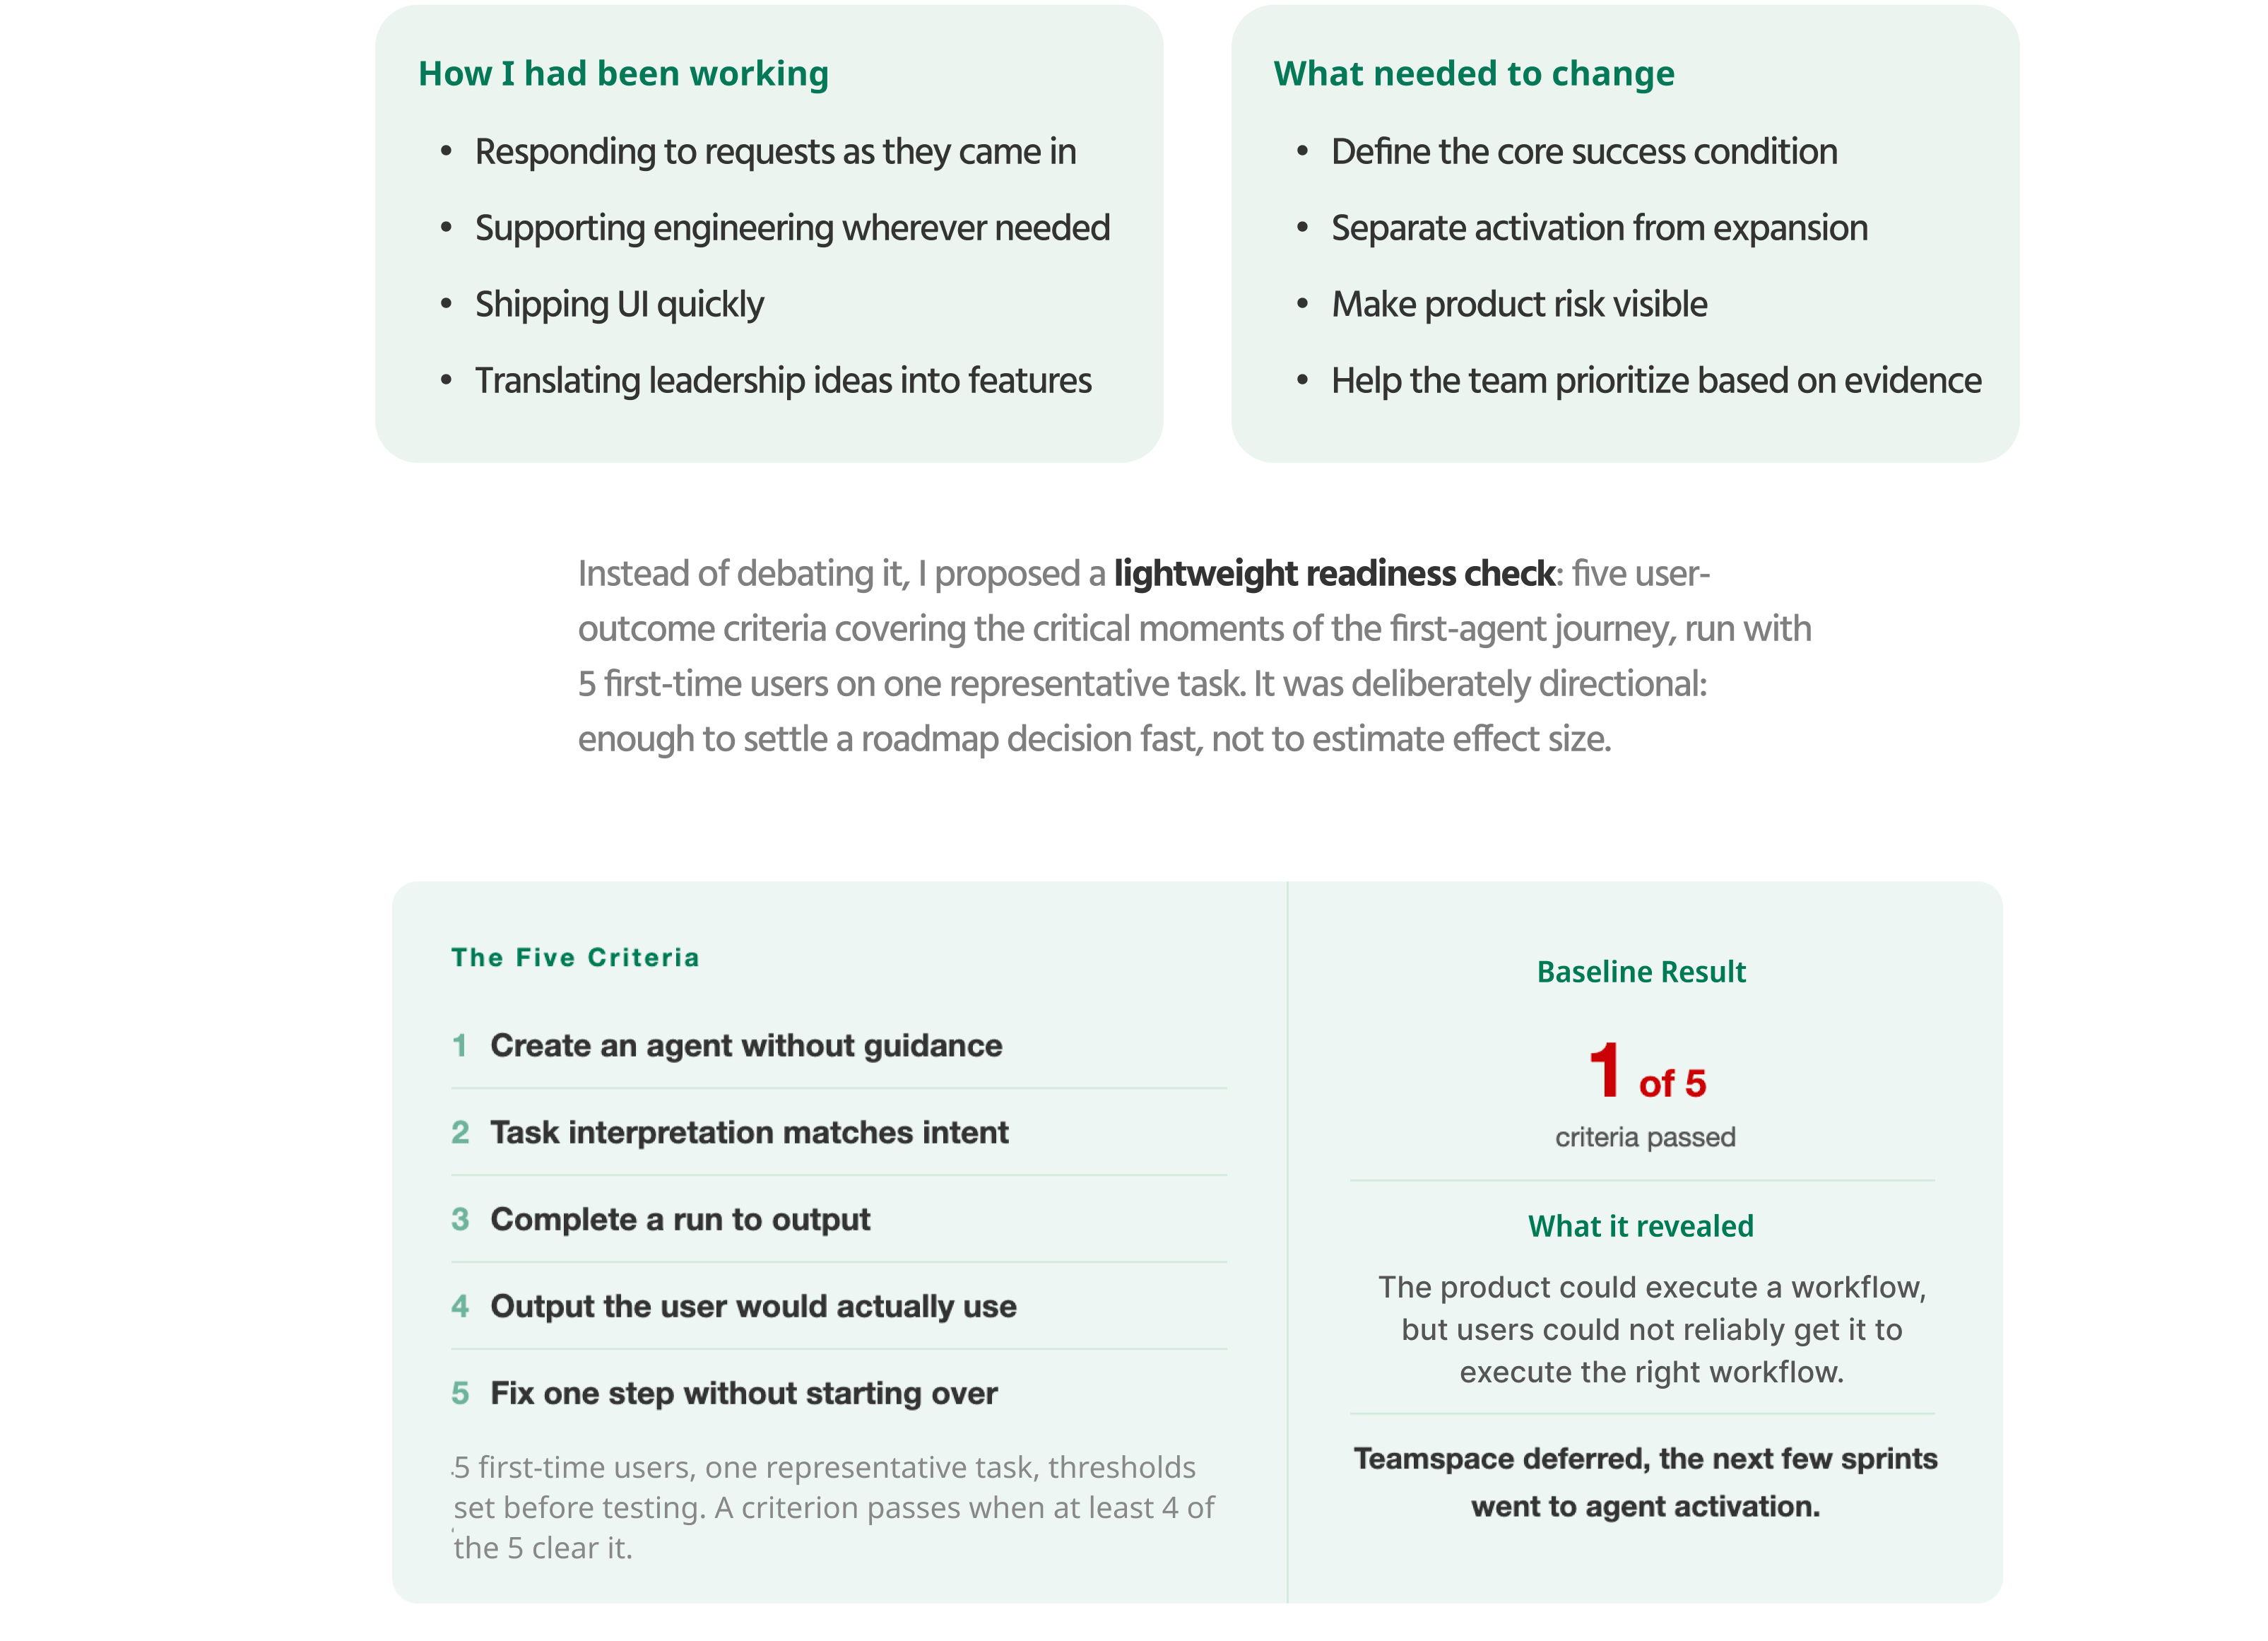
Until then I had been optimizing for shipping speed, and speed alone was not solving user success. The proposal forced me to change how I worked:
– The Benchmark –
The check changed the roadmap. Testing revealed its blind spot
It worked as a fast go/no-go, but the testing also showed that interface usability alone was not enough to measure AI product readiness. Users could complete the flow while the AI still misunderstood the task or generated an unusable result, and an average score could hide the two failures that mattered most.
What it did well
- Fast go / no-go signal
- Made activation risk visible
- Redirected the roadmap
What it missed
- Completing the UI ≠ the AI product is ready
- Model failures are part of the experience
- A total score hides critical outcome failures
How I strengthened it
- Criteria grouped by Intent / Mechanism / Outcome
- 80% threshold on every criterion
- Match intent and Useful output must pass, with no averaging around them
Score decided readiness. Failure attribution decided what to change next.
– The Redesigns –
I broke the setup into smaller steps. The cognitive load stayed
The first hypothesis was that users knew the context the agent needed and just needed a less overwhelming way to give it. So instead of asking for goal, inputs, outputs, files and sources at once, I split setup into guided steps.
Tested against the revised gate with 34 users, it failed. Smaller steps reduced visual overwhelm, not the cognitive burden of defining the task. Only 1 of 5 criteria passed, and both must-pass outcomes failed: Match intent 41.2%, Useful output 38.2%.
The question became where structure should live
The prompt-driven flow asked too little. The structured setup asked too much. The decision was how to collect enough context without making users configure the workflow themselves.
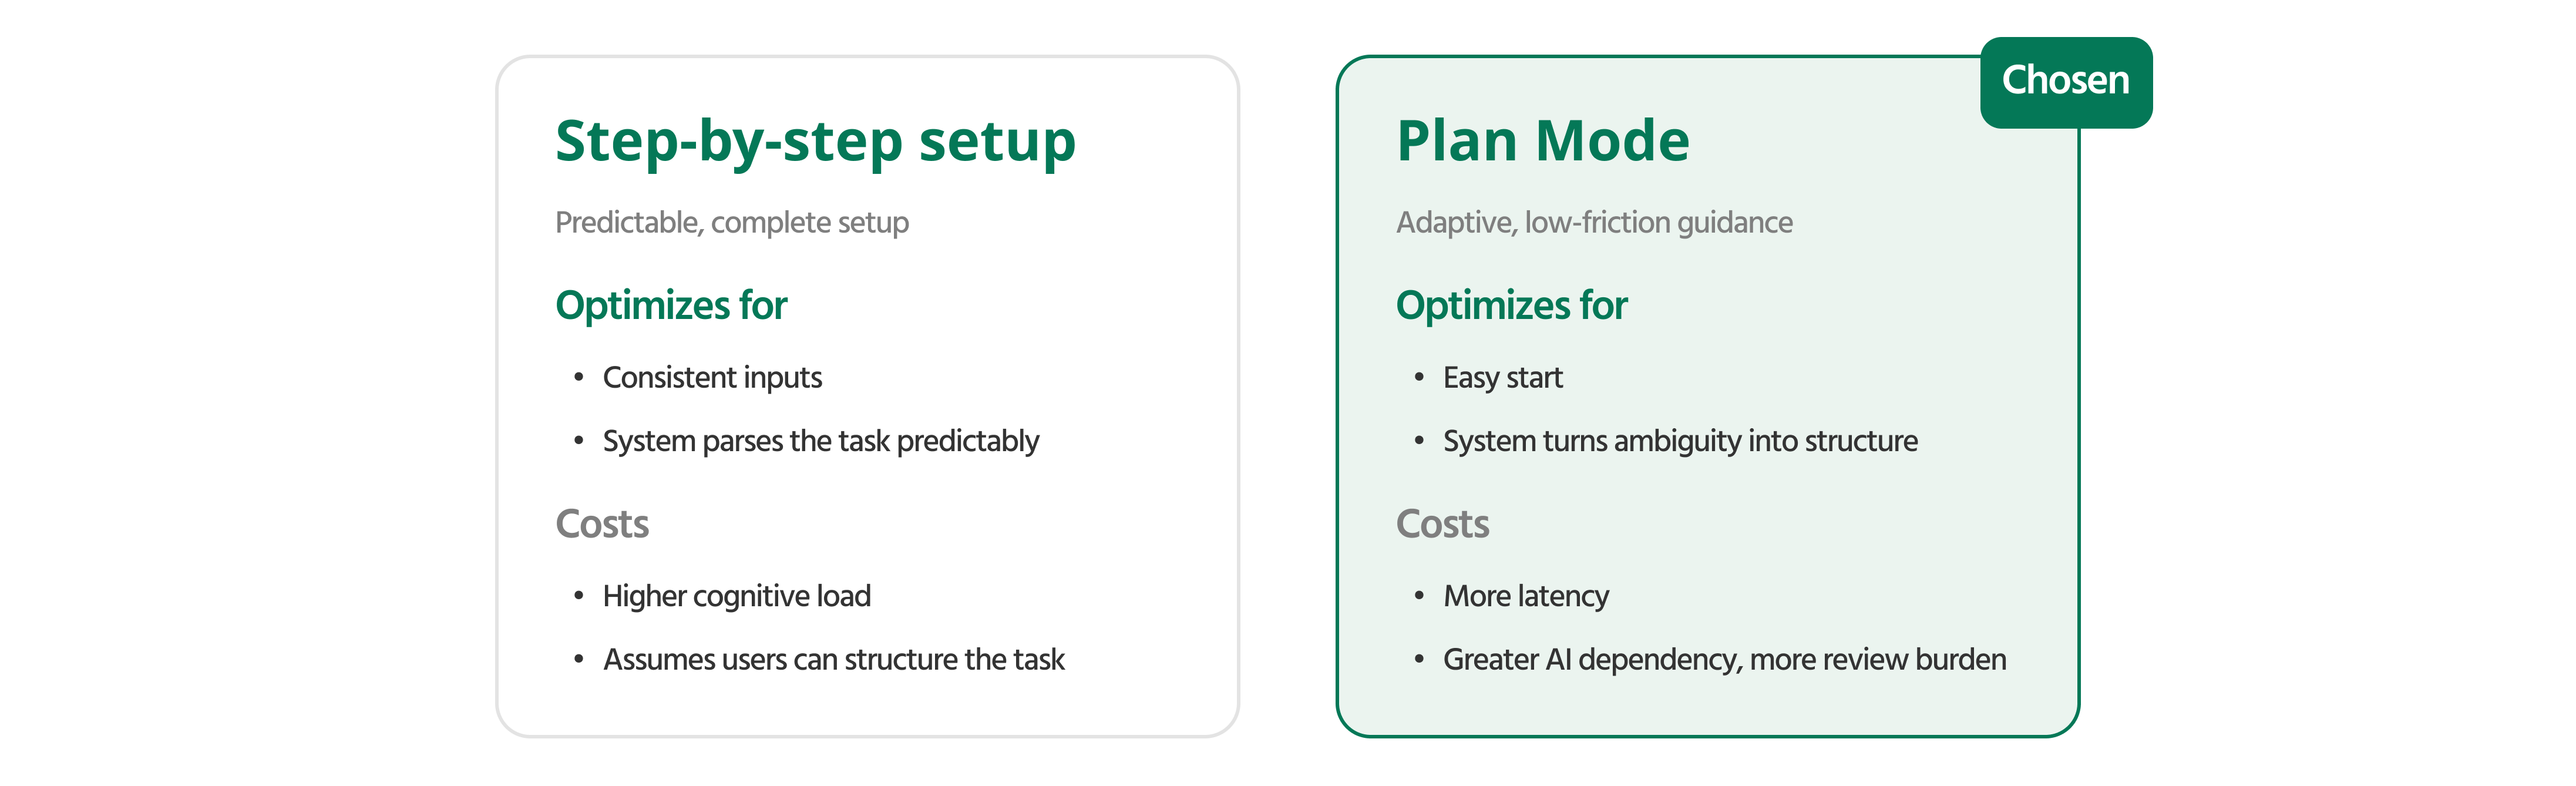
Decision: reduce structure during input, then restore it before execution through a reviewable plan.
Alignment before execution
Plan Mode keeps the lightweight starting point, but makes the agent’s interpretation visible and editable before the workflow runs: it asks only what it needs, then restates the goal and outlines the steps for the user to confirm.
The team worried the extra step would hurt time-to-first-result. It didn’t: every user still completed their run, and Match intent went from 41.2% to 96.4%. A ten-second review beat a misaligned full run.
Two further changes evolved alongside, validated as part of the same experience:
Reconstructing workflow execution around clarity and control
Users couldn’t tell how nodes connected, where each step’s output lived, or what to do when something failed, so I rebuilt execution around clear step sequences, step-level outputs, and direct retry controls.
Creation as briefing a specialist team
Researchers already delegated analysis to specialists, so configuring an agent still felt too technical. I reframed each workflow step as a named specialist, making the experience feel more like delegating work to colleagues. Users could give each specialist files, context, or instructions, then @-mention one to refine a specific step without starting over.
One rule held across all three: every agent behavior gets a visible, editable representation. The plan before a run, the steps during it, the specialists behind it.
This was also where my toolchain shifted: after validating the flow, I shipped the frontend to production myself (Claude Code for the build) and have kept shipping production features since.
– Final Product –
– The Proof –
The complete experience cleared the revised gate
Same five criteria, same 80% threshold, same two mandatory outcomes, measured before and after the redesign.
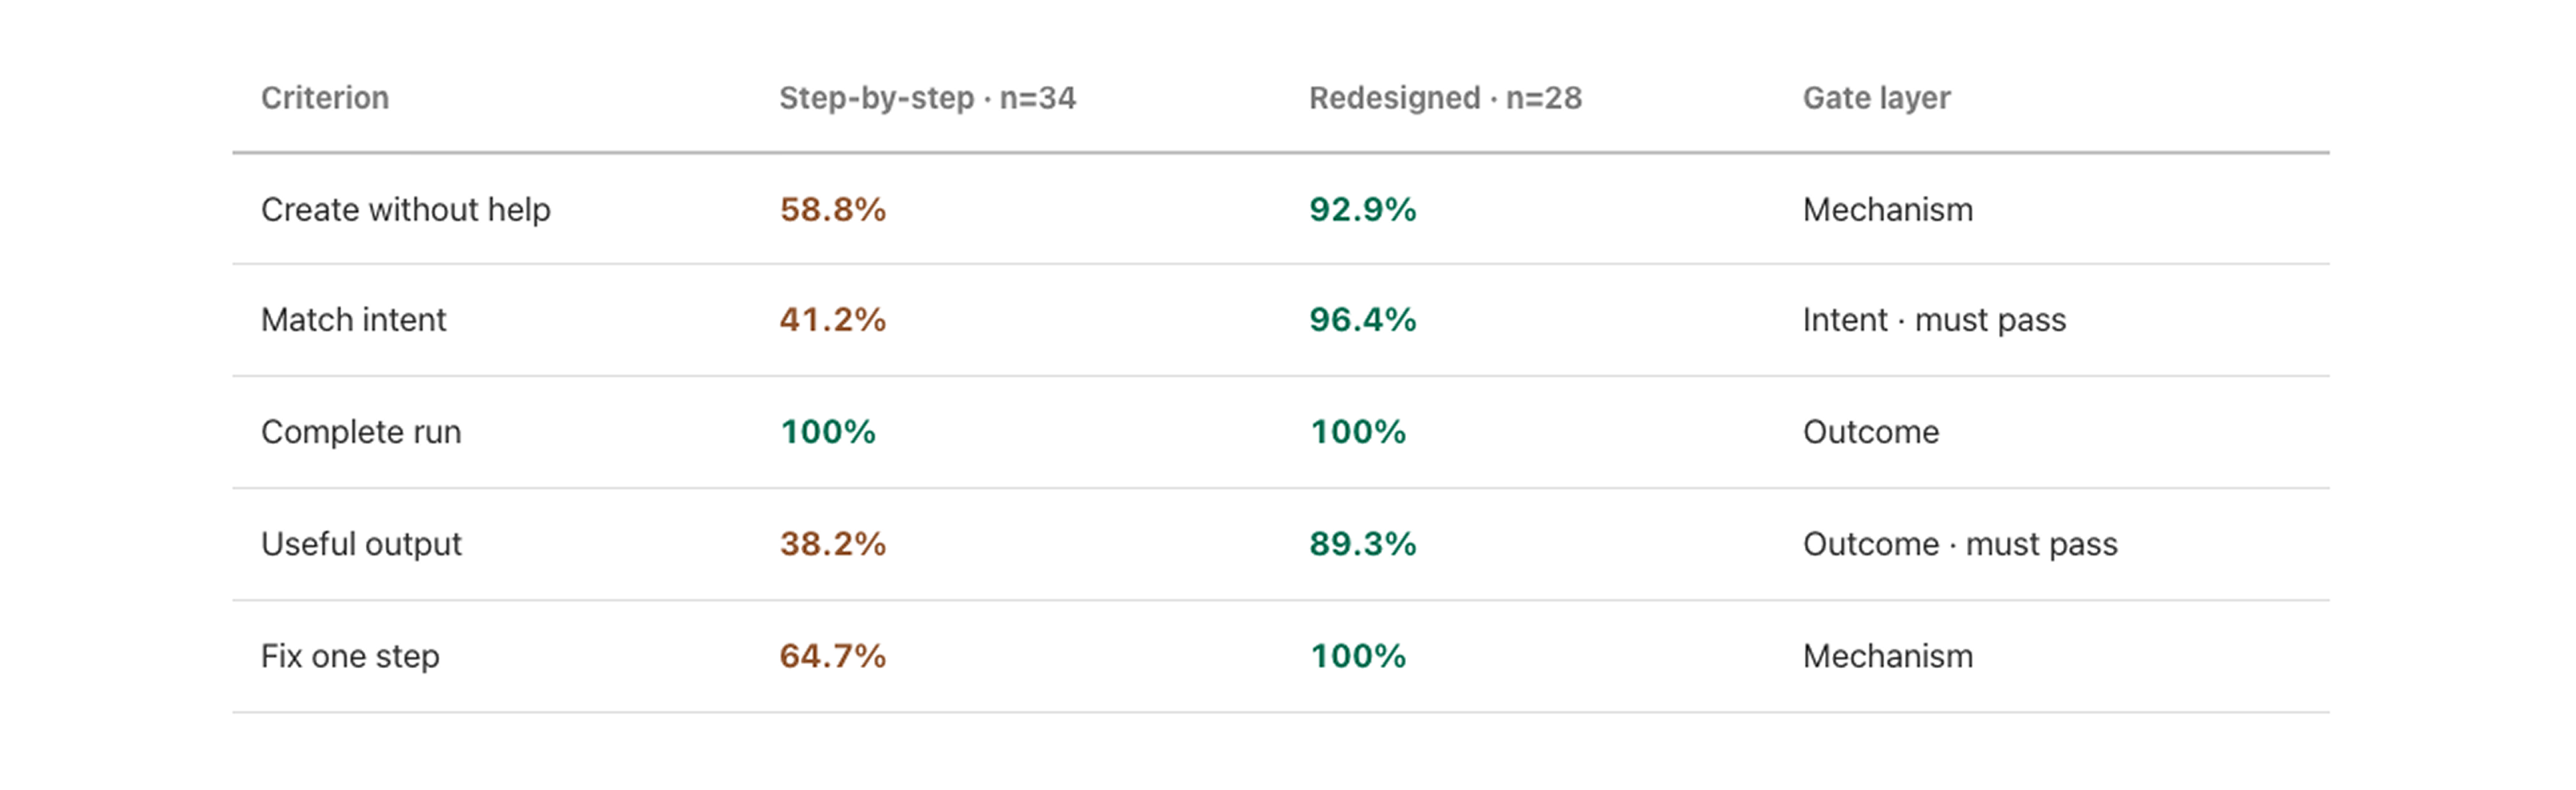
Both must-pass outcomes moved from failing to clearing. Scores reflect the complete product experience, not any single feature.
1 of 5 → 5 of 5
criteria passed against the revised gate
Both must-pass
outcomes cleared the 80% threshold
n = 28
moderated end-to-end validation
– The Outcome –
Launched, then adopted beyond the audience it was built for
AgentLab launched publicly. We built it for researchers, but analysts, report writers, and finance teams around the world picked it up too. The problem turned out to be universal: people can’t trust an answer when they can’t check the work behind it.
User Impact
5 of 5
readiness criteria passed, up from 1 of 5
Product Impact
6 months
demo to launch; Plan → Review → Run became the pattern for new surfaces
Reach
30,000+
registered users after launch across the US, China, Mexico and beyond
And Teamspace? It never shipped. Post-launch, fewer than 1.5% of users shared an agent. The gate saved us from building a feature nobody was ready for.
– The Takeaways –
What I learned
1. Define the success condition before opening Figma
If first-agent success had been defined a quarter earlier, the scorecard would have existed before Teamspace was ever proposed.
2. AI product readiness goes beyond usability
Users may operate the interface correctly while the model misunderstands the task or generates an unusable result. For AI products, we need to evaluate both how people use the experience and what the system ultimately produces.
3. Use the right level of rigor for the decision
A lightweight check was enough to redirect the roadmap. Broader validation required a formalized protocol, applied consistently across V1 and V2.